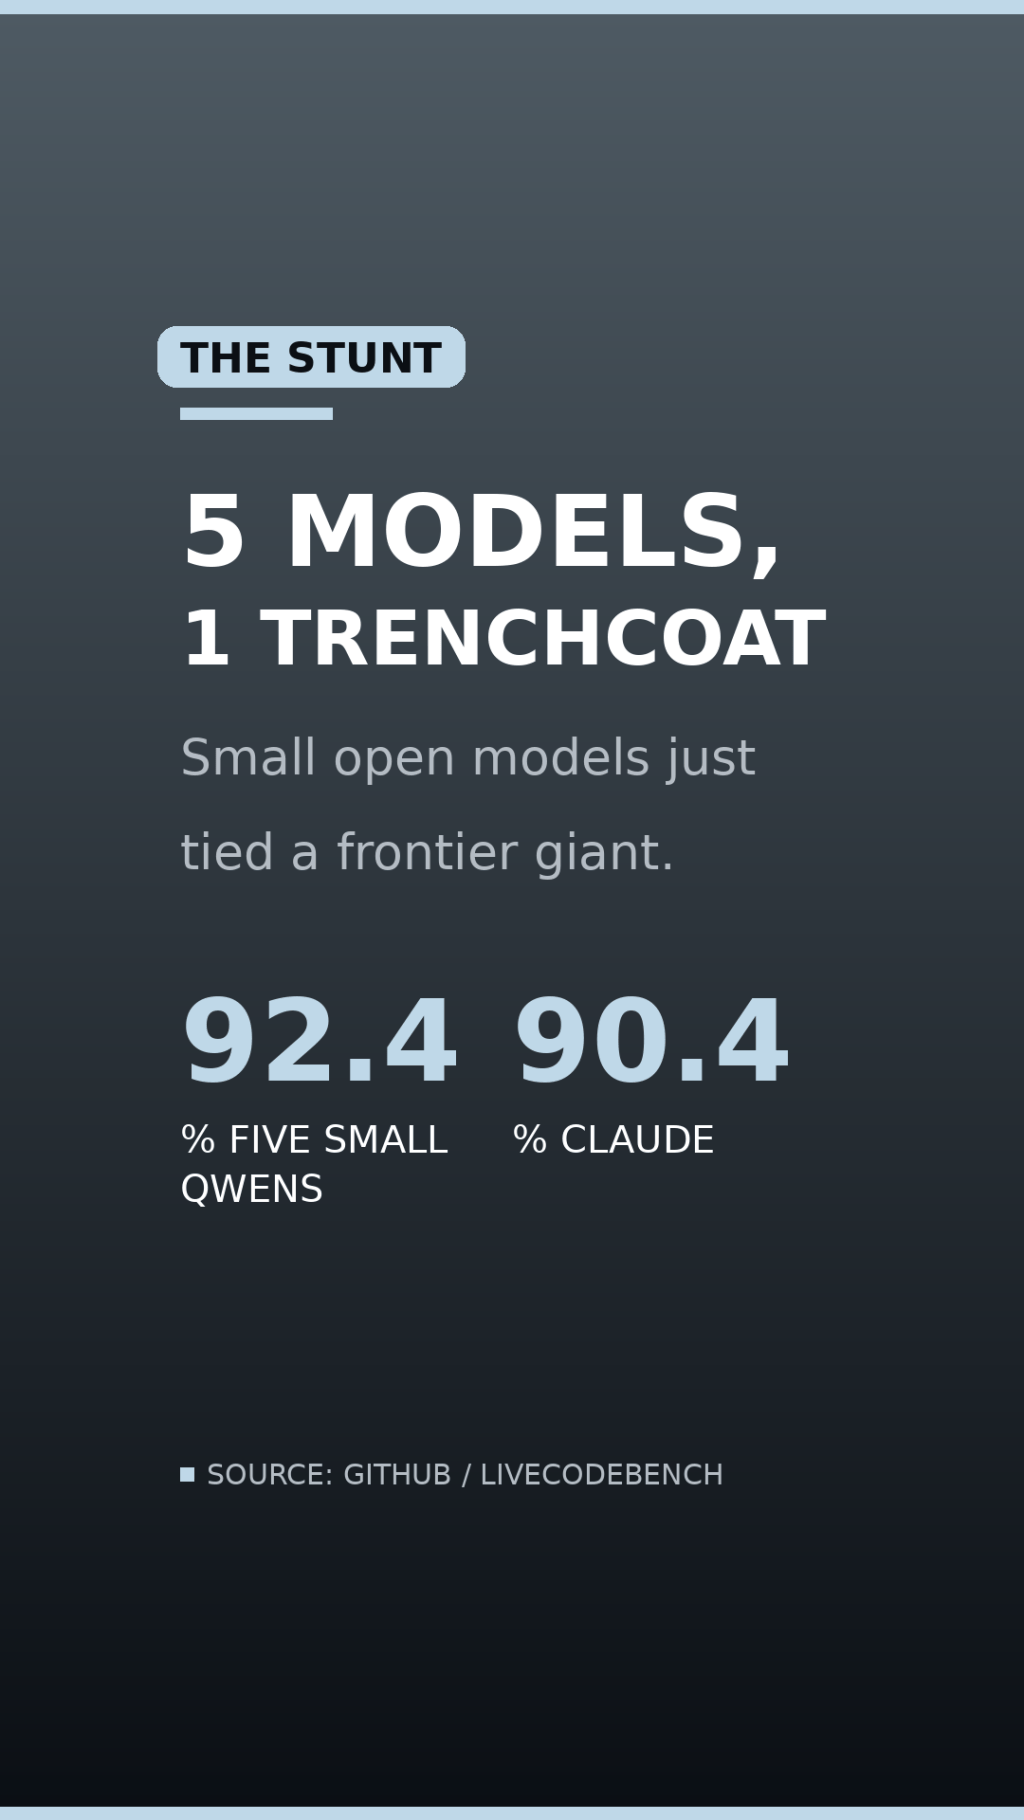
Five small open models in a trenchcoat just tied Claude. Five Qwen 3.8-27B instances sharing one workspace scored 92.4% on LiveCodeBench hard, against Claude Fable 5’s 90.4%. The catch: an agentic loop on a single-pass benchmark isn’t a fair fight — but the cost story is real, and it runs locally.
Storyline:
Hook: Five tiny open models — without a billion-dollar budget — just scored 92.4% on hard coding tests. Claude scored 90.4%.
Context: The GitHub project GVS5H runs five Qwen3.8-27B instances through a shared workspace — planner, workers, verifier — scoring 92.4% on LiveCodeBench hard vs Claude Fable 5’s 90.4%.
Stakes: An agentic loop on a single-pass benchmark isn’t a fair fight, the benchmark saturated in 2025, and there are no numbers vs Astra, Sol, or Opus 5.5.
Payoff: But the cost story is real — small models, orchestrated well, running locally, can match a frontier giant on its own test.
Links:
Watch the reel: https://www.instagram.com/p/De7sXauAceE/
Source: GitHub / LiveCodeBench
Instagram: https://www.instagram.com/simpleaiexplains/
Support: https://buymeacoffee.com/simpleaiexplains


Leave a Reply